LLM Landscape 2026: Intelligence Leaderboard and Model Guide
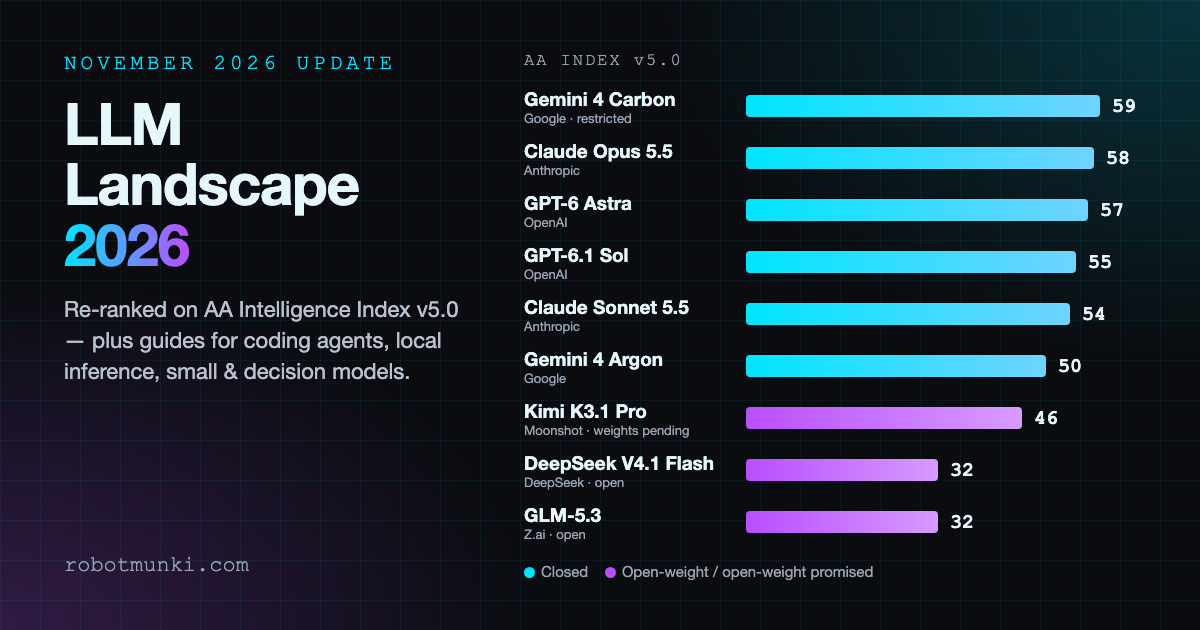
A November 2026 snapshot of the LLM landscape. The yardstick changed this cycle: Artificial Analysis retired the v4.1 index this leaderboard used in August and, after two interim versions, launched Intelligence Index v5.0 on October 27 — so every score below is re-based and none of them compare with August's numbers. On v5.0, Google's Gemini 4 Carbon (59) leads but is limited to vetted cyber defenders; Claude Opus 5.5 (58) is the best model you can actually use; GPT-6.1 Sol (55) is the value pick at roughly an eighth of Opus 5.5's cost per task. August's headline — open weights one point from the top — has reversed: the best downloadable open-weight models now sit at 32. After the leaderboards, the guide is reorganized by use case: coding agents, agentic automation, self-hosting, local inference, small models, decision models, speed, long context, budget, and sovereign deployments.
Contents
- Leaderboard methodology
- Leaderboard by vendor · Top 25 by model
- What changed since August
- Quick picks
- Use-case guides: frontier reasoning · coding agents · agentic automation · open-weight self-hosting · local inference · small & edge · decision & routing · speed · long context · budget APIs · sovereign & regional
Leaderboard Methodology
Both tables use the Artificial Analysis (AA) Intelligence Index v5.0 (launched Oct 27, 2026). It averages four equally weighted categories — knowledge work (AA-Briefcase, AutomationBench-AA, GDP.pdf), coding (FrontierCode 2.0, Terminal-Bench 4.0), science (Terminal-Bench-Science, CritPt v2), and general (AA-Omniscience v1.1, HLE-Diamond) — and about 60% of its test data is private or held out. v5.0 dropped GPQA Diamond, SciCode, AA-LCR, and GDPval, and it penalizes models that rely on saturated public benchmarks; open-weight models lost noticeably more ground than closed ones in the switch.Scores use each model's best published effort setting. A dash (—) means the model has no v5.0 score yet — usually because it launched before Oct 27 and AA hasn't re-run it, or because AA can't reach a public API. Pricing is USD per million tokens (input / output) at the standard tier; tiered, off-peak, and promo prices are noted. Access-restricted models (Gemini 4 Carbon, Claude Mythos 5.1) are included with notes because they shape the competitive picture.Leaderboard by Vendor — One Model per Lab (November 2026)
Each lab's strongest current model, to show how broad the field is. Labs whose best model isn't on v5.0 yet are listed after the ranked entries.| Rank | Model | Capability Index (AA v5.0) | Context Window (tokens) | Input Cost ($/M tokens) | Output Cost ($/M tokens) | Notes |
|---|---|---|---|---|---|---|
| 1 | Gemini 4 Carbon Google | 59 | 1,000,000 | $4.00 | $20.00 | New Oct 28 #1 on AA v5.0, but access is limited to vetted cyber defenders (Fairwind); no developer or consumer date yet |
| 2 | Claude Opus 5.5 Anthropic | 58 | 1,000,000 | $4.00 | $20.00 | New Sep 22 Best generally-available model on AA v5.0; leads FrontierCode 2.0 (46%), HLE-Diamond and Omniscience; price cut from Opus 5's $5/$25 |
| 3 | GPT-6 Astra OpenAI | 57 | 1,050,000 | $10.00 | $50.00 | New Sep 3 Leads Terminal-Bench-Science (63%) and CritPt v2 (72%); access reportedly gated on cyber-safety grounds; GPT-6.1 Astra was shelved |
| 4 | Muse Wonder Full Meta | 50 | 1,000,000 | — | — | New Oct 12 Meta's frontier line is now Muse, not Llama; Full has no API (Muse Code subscriptions only); API variant Muse Wonder scores 43 at $4/$20 |
| 5 | Kimi K3.1 Pro Moonshot AI | 46 | 1,048,576 | $2.00 | $10.00 | New Oct 23 Leads Terminal-Bench 4.0 (67%); 2.8T / 104B active; weights promised for Nov 4 but not yet published |
| 6 | Grok 4.7 xAI (SpaceXAI) | 35 | 500,000 | $2.00 | $6.00 | New Sep 21 Strong on v4.3.2 (46) but 35 on v5.0; no xAI model in the v5 top 30 |
| 7 | Qwen3.8 Max Alibaba | 34 | 984,000 | $2.00 | $6.00 | AA now lists the API model separately from the open 2.4T-A95B weights (no v5 score); Qwen4 previewed Oct 29, launch expected imminently |
| 8 | DeepSeek V4.1 Flash-1017 DeepSeek AI | 32 | 1,000,000 | $0.30 | $1.20 | New Oct 17 Open Weight Co-#1 downloadable open-weight model on v5.0; MIT; multimodal; ~16B active; off-peak $0.15/$0.60 |
| 9 | GLM-5.3 Z.ai | 32 | 1,000,000 | $1.40 | $4.40 | Open Weight Co-#1 downloadable open-weight model on v5.0; weights on HF since Aug 28 (custom GLM license); 60 on the retired v4.1 |
| 10 | MiMo-V2.6-Pro Xiaomi | 30 | 1,000,000 | $0.43 | $0.87 | New Sep 21 Open Weight Topped open weights on v4.3 (46); MIT; 1T / 42B active; Flash sibling at $0.14/$0.28 |
| 11 | Ling 3.1 Flash-1019 InclusionAI (Ant) | 29 | 1,000,000 | $0.30 | $0.90 | New Oct 22 Open Weight MIT; 560B / 25B active |
| 12 | MiniMax-M3.1-Flash MiniMax | 29 | 1,000,000 | $0.15 | $0.60 | New Oct 19 Open Weight 428B / 23B active; image + video input; weights Oct 23 (community license) |
| 13 | Step 5 Preview StepFun | 29 | 1,000,000 | — | — | New Oct 15 Open Weight 600B / 27B active; text + vision; open weights mid-October |
| 14 | Mistral Large 4 Mistral | 26 | 1,000,000 | $0.70 | $2.10 | New Oct 6 Open Weight ~1T / 52B active, multimodal, 160+ languages; weights Oct 29 under a modified-MIT open-weight license; verbose |
| 15 | Reflection Beam 1.0 Reflection AI | 18 | 1,000,000 | — | — | New Oct 5 Open Weight Apache 2.0; 501B / 23B active; weights Oct 16; 30 at launch on v4.3 |
| 16 | K2 Horizon 375B MBZUAI IFM | 18 | 524,000 | — | — | New Sep 3 Open Weight Fully open — weights, data, and training code; Apache 2.0 |
| 17 | Nemotron 3.5 Super VL NVIDIA | 14 | 1,000,000 | — | — | New Oct 15 Open Weight 120B / 12B active; text + image + video; open data and recipes |
| 18 | Inkling Thinking Machines | 12 | 1,000,000 | — | — | Open Weight 975B / 41B active, Apache 2.0; 41 at launch on v4.1 |
| 19 | Hunyuan Hy4-preview Tencent | — | 1,000,000 | $0.83 | $2.50 | Open Weight Apache 2.0; 770B / 49B active; not yet scored by AA (price via OpenRouter) |
| 20 | Mercury 2.5 Inception | — | 260,000 | $0.20 | $0.75 | New Sep 8 Diffusion LLM, ~1,107 tok/s (vendor); promo $0.04/$0.15; no AA score yet |
| 21 | Kolibri-1 Aleph Alpha | — | 256,000 | — | — | New Oct 3 Open Weight Sovereign EN/DE model; 78B / 3.46B active; Apache 2.0; trained at 256K (1M supported); not yet on AA |
Top 25 Models by AA Index v5.0 — Pure Capability (November 2026)
Ranked by score regardless of vendor. Expect several entries each from OpenAI, Anthropic, and Google.| Rank | Model | Capability Index (AA v5.0) | Context Window (tokens) | Input Cost ($/M tokens) | Output Cost ($/M tokens) | Notes |
|---|---|---|---|---|---|---|
| 1 | Gemini 4 Carbon Google | 59 | 1,000,000 | $4.00 | $20.00 | New Oct 28 #1 on AA v5.0, but access is limited to vetted cyber defenders (Fairwind); no developer or consumer date yet |
| 2 | Claude Opus 5.5 Anthropic | 58 | 1,000,000 | $4.00 | $20.00 | New Sep 22 Best generally-available model on AA v5.0; leads FrontierCode 2.0 (46%), HLE-Diamond and Omniscience; price cut from Opus 5's $5/$25 |
| 3 | GPT-6 Astra OpenAI | 57 | 1,050,000 | $10.00 | $50.00 | New Sep 3 Leads Terminal-Bench-Science (63%) and CritPt v2 (72%); access reportedly gated on cyber-safety grounds; GPT-6.1 Astra was shelved |
| 4 | GPT-6.1 Sol OpenAI | 55 | 1,000,000 | $2.00 | $10.00 | New Sep 29 Best value at the frontier: ~$1.27 to run the full AA index vs ~$10 for Opus 5.5 max |
| 5 | Claude Sonnet 5.5 Anthropic | 54 | 1,000,000 | $2.00 | $10.00 | New Leads AA-Briefcase (knowledge work, 1,812 Elo); very token-hungry at max effort |
| 6 | GPT-6.1 Terra OpenAI | 51 | 1,000,000 | $1.00 | $5.00 | New Oct 26 Mid-tier at $1/$5 that out-scores Gemini 4 Argon |
| 7 | Gemini 4 Argon Google | 50 | 1,000,000 | $2.00 | $10.00 | New Oct 13 GA Oct 13; replaces the cancelled Gemini 3.5 Pro; 1M output limit; leads AutomationBench-AA (78%); intro price rises to $4/$20 on Dec 1 |
| 8 | Claude Fable 5.1 Anthropic | 50 | 1,000,000 | $10.00 | $50.00 | GA Sep 1 Now generally available; topped the retired v4.1 index (66) but scores 50 on v5.0; xhigh outscores max |
| 9 | Muse Wonder Full Meta | 50 | 1,000,000 | — | — | New Oct 12 Meta's frontier line is now Muse, not Llama; Full has no API (Muse Code subscriptions only); API variant Muse Wonder scores 43 at $4/$20 |
| 10 | Kimi K3.1 Pro Moonshot AI | 46 | 1,048,576 | $2.00 | $10.00 | New Oct 23 Leads Terminal-Bench 4.0 (67%); 2.8T / 104B active; weights promised for Nov 4 but not yet published |
| 11 | Muse Wonder Meta | 43 | 1,048,576 | $4.00 | $20.00 | New Oct 12 API preview; Meta Model API speaks both OpenAI and Anthropic formats |
| 12 | Claude Haiku 5.5 Anthropic | 36 | 1,000,000 | $0.10 | $0.50 | New $0.10/$0.50 up to 100K-token prompts ($0.50/$2.50 above); beats every released open-weight model on v5.0 |
| 13 | Grok 4.7 xAI (SpaceXAI) | 35 | 500,000 | $2.00 | $6.00 | New Sep 21 Strong on v4.3.2 (46) but 35 on v5.0; no xAI model in the v5 top 30 |
| 14 | Qwen3.8 Max Alibaba | 34 | 984,000 | $2.00 | $6.00 | AA now lists the API model separately from the open 2.4T-A95B weights (no v5 score); Qwen4 previewed Oct 29, launch expected imminently |
| 15 | DeepSeek V4.1 Flash-1017 DeepSeek AI | 32 | 1,000,000 | $0.30 | $1.20 | New Oct 17 Open Weight Co-#1 downloadable open-weight model on v5.0; MIT; multimodal; ~16B active; off-peak $0.15/$0.60 |
| 16 | GLM-5.3 Z.ai | 32 | 1,000,000 | $1.40 | $4.40 | Open Weight Co-#1 downloadable open-weight model on v5.0; weights on HF since Aug 28 (custom GLM license); 60 on the retired v4.1 |
| 17 | Gemini 3.8 Flash Google | 31 | 1,000,000 | $0.75 | $3.75 | New Sep 2 Intro pricing through Dec 31, then $1.50/$7.50; gemini-2.5-pro traffic reroutes here from Dec 1 |
| 18 | MiMo-V2.6-Pro Xiaomi | 30 | 1,000,000 | $0.43 | $0.87 | New Sep 21 Open Weight Topped open weights on v4.3 (46); MIT; 1T / 42B active; Flash sibling at $0.14/$0.28 |
| 19 | Ling 3.1 Flash-1019 InclusionAI (Ant) | 29 | 1,000,000 | $0.30 | $0.90 | New Oct 22 Open Weight MIT; 560B / 25B active |
| 20 | MiniMax-M3.1-Flash MiniMax | 29 | 1,000,000 | $0.15 | $0.60 | New Oct 19 Open Weight 428B / 23B active; image + video input; weights Oct 23 (community license) |
| 21 | Step 5 Preview StepFun | 29 | 1,000,000 | — | — | New Oct 15 Open Weight 600B / 27B active; text + vision; open weights mid-October |
| 22 | Mistral Large 4 Mistral | 26 | 1,000,000 | $0.70 | $2.10 | New Oct 6 Open Weight ~1T / 52B active, multimodal, 160+ languages; weights Oct 29 under a modified-MIT open-weight license; verbose |
| 23 | Muse Spark Open Meta | 25 | 1,000,000 | — | — | New Oct 15 Open Weight Open weights (Muse Model License); 816B / 42B active; replaces Llama as Meta's open flagship |
| 24 | DeepSeek V4 Pro-0813 DeepSeek AI | 23 | 1,000,000 | $1.32 | $3.96 | Open Weight Price cut ~40–55%; now out-scored by V4.1 Flash; V4.1 Pro named but unreleased |
| 25 | Qwen3.8 27B Alibaba | 20 | 256,000 | $0.43 | $2.55 | Open Weight Best single-GPU dense open model on v5.0 |
What Changed Since August
- The index changed three times. AA moved from v4.1 to v4.2 (Sep 4), v4.3 (Sep 7), and v5.0 (Oct 27). The August table's 61s and 60s don't map to anything on today's scale; the top score is now 59.
- A new #1, with an asterisk. Gemini 4 Carbon (Oct 28, 59) leads, but only vetted cyber defenders can use it. Claude Opus 5.5 (Sep 22, 58) is the best generally available model — and it's cheaper than the Opus 5 it replaces ($4/$20 vs $5/$25).
- OpenAI's GPT-6 generation landed. GPT-6 Astra (Sep 3, 57) is the flagship; GPT-6.1 Sol (Sep 29, 55, $2/$10) and GPT-6.1 Terra (Oct 26, 51, $1/$5) are the value story. A planned GPT-6.1 Astra was reportedly shelved over safety concerns.
- Anthropic refreshed the whole lineup. Fable 5.1 went GA (Sep 1); Opus, Sonnet, and Haiku all moved to 5.5; every current Claude model has a 1M context window; Haiku 5.5 introduced tiered pricing ($0.10/$0.50 up to 100K-token prompts).
- Google skipped a generation. Gemini 3.5 Pro was cancelled (Sep 30). Gemini 4 Argon went GA on Oct 13 at $2/$10 intro pricing (rising to $4/$20 on Dec 1) with a 1M output limit; Gemini 3.8 Flash replaced 3.7 Flash on Sep 2.
- Meta's frontier line is now Muse. Muse Wonder (API, 43) and Muse Wonder Full (subscription only, 50) are closed; Muse Spark Open (Oct 15, 25) replaces Llama as Meta's open flagship.
- xAI fell out of the top tier. Grok 4.7 (Sep 21) scored 46 on v4.3.2 but 35 on v5.0 — no xAI model is in the v5 top 30.
- The open-weight gap reversed. In August, GLM-5.3 and Kimi K3 were one point behind the leader. On v5.0, the best open-weight models you can download today (DeepSeek V4.1 Flash-1017 and GLM-5.3) score 32 — 26 points behind Opus 5.5. Kimi K3.1 Pro (Oct 23, 46) would cut that to 12 once Moonshot publishes the promised weights.
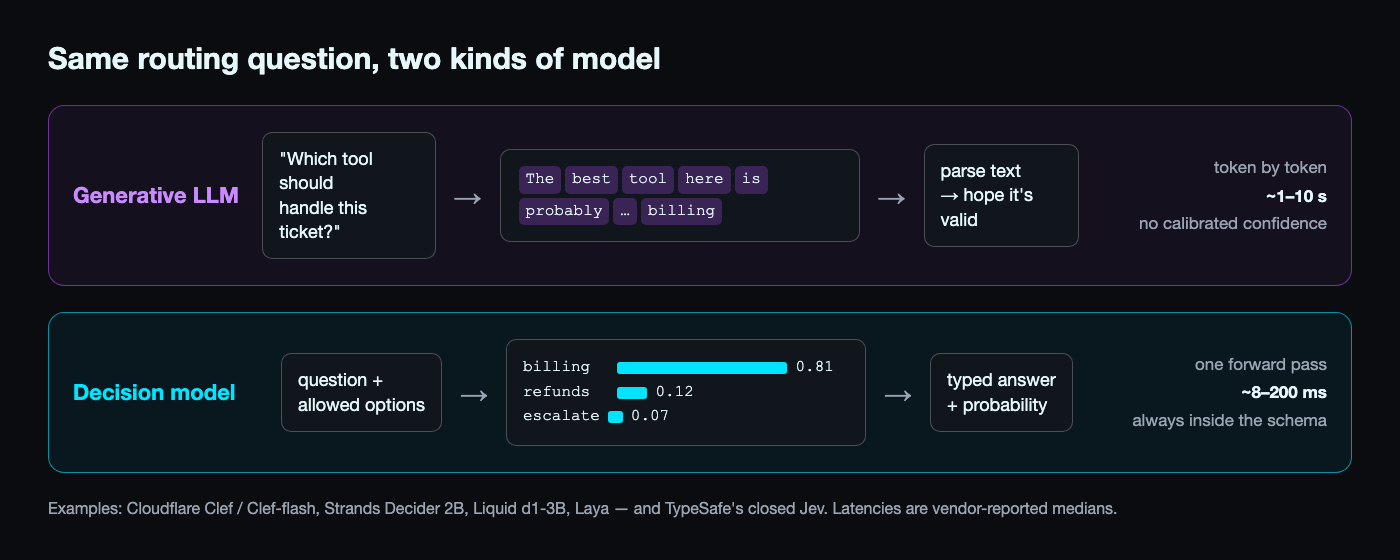
- A new category: decision models. Cloudflare Clef, Strands Decider, Liquid d1, and Laya return calibrated choices instead of text — see decision & routing and the October new-models roundup.
Quick Picks
| If you need… | Pick | Runner-up | Why |
|---|---|---|---|
| The smartest model you can use today | Claude Opus 5.5 | GPT-6 Astra | 58 on AA v5.0; leads FrontierCode 2.0 and HLE-Diamond |
| Frontier quality on a budget | GPT-6.1 Sol | GPT-6.1 Terra | 55 for ~$1.27 per full AA index run |
| A daily coding agent | Claude Sonnet 5.5 | GPT-6.1 Sol | Strong coding + knowledge work at $2/$10 |
| Terminal-heavy / long agent loops | Kimi K3.1 Pro | Claude Opus 5.5 | #1 on Terminal-Bench 4.0 (67%) at $2/$10 |
| Office / workflow automation | Gemini 4 Argon | Claude Sonnet 5.5 | Leads AutomationBench-AA; 1M output tokens |
| Best open weights to self-host | DeepSeek V4.1 Flash-1017 | GLM-5.3 | Co-#1 downloadable (32), MIT, only 16B active |
| A model on one GPU | Qwen3.8 27B | Gemma 4 31B | Best single-GPU dense model on v5.0 (20) |
| On a laptop or phone | Gemma 4 12B / E4B | Liquid d1-3B (decisions) | Small, multimodal, Apache 2.0 |
| Routing, classification, guardrails | Cloudflare Clef-flash | Liquid d1-3B | Typed, calibrated answers in milliseconds |
| Cheapest capable hosted model | Claude Haiku 5.5 | DeepSeek V4.1 Flash-1017 | 36 on v5.0 at $0.10/$0.50 |
| Raw generation speed | Mercury 2.5 | Gemini 3.8 Flash | Diffusion LLM, ~1,100 tok/s (vendor-reported) |
| EU-hosted / sovereign | Mistral Large 4 | Aleph Alpha Kolibri-1 | Open weights, EU-trained, 160+ languages |
Frontier Reasoning & Knowledge Work
The top of the board is a three-way race between Anthropic, OpenAI, and Google, with Meta's subscription-only Muse Wonder Full close behind. Differences of one or two points are within run-to-run noise; pick on strengths, access, and cost per task.| Model | AA v5.0 | $/M in / out | Pick it when |
|---|---|---|---|
| Claude Opus 5.5 | 58 | $4 / $20 | You want the best available all-rounder; leads FrontierCode 2.0, HLE-Diamond, and AA-Omniscience (fewest confident wrong answers) |
| GPT-6 Astra | 57 | $10 / $50 | Science and research — leads Terminal-Bench-Science (63%) and CritPt v2 (72%) |
| GPT-6.1 Sol | 55 | $2 / $10 | You need near-frontier quality across lots of calls; most cost-efficient model in the top 10 |
| Claude Sonnet 5.5 | 54 | $2 / $10 | Knowledge work — leads AA-Briefcase (1,812 Elo) — but watch token use at max effort |
| Gemini 4 Argon | 50 | $2 / $10 → $4 / $20 Dec 1 | Long outputs (1M output limit), video, and Google Workspace-heavy workflows |
| Gemini 4 Carbon | 59 | $4 / $20 | Only if you're a vetted cyber defender — there is no public access date |
Coding Agents
SWE-bench Verified is saturated — top models score in the 90s and most labs have stopped reporting it. The useful signals now are FrontierCode 2.0 (hard, private, repo-scale tasks), Terminal-Bench 4.0 (long shell-driven agent loops), and DeepSWE v1.1. Just as important is tokens per task: an agent that solves the same issue with half the tokens is half the price.| Model | Best at | Evidence | $/M in / out |
|---|---|---|---|
| Claude Opus 5.5 | Hardest repo-scale changes | #1 FrontierCode 2.0 (46%) | $4 / $20 |
| Kimi K3.1 Pro | Terminal / long-horizon agent loops | #1 Terminal-Bench 4.0 (67% AA-measured) | $2 / $10 |
| Claude Sonnet 5.5 | Daily driver in Claude Code / Cursor-style tools | 54 overall; strong on both coding evals | $2 / $10 |
| GPT-6.1 Sol | Cheap, fast agent loops at scale | 55 overall at ~$1.27 per index run | $2 / $10 |
| Fireworks Ember-1 | Cutting Kimi K3 agent costs | Matches K3 on SWE-bench / Terminal-Bench with 35–71% fewer reasoning tokens (vendor) | ~$3 / $15 |
| DeepSeek V4.1 Flash-1017 | Open-weight coding on a budget | DeepSWE v1.1 77.0 (vendor); MIT | $0.30 / $1.20 |
| GLM-5.3 / MiMo-V2.6-Pro | Self-hosted coding agents | 32 / 30 on v5.0; open weights | $1.40 / $4.40 · $0.435 / $0.87 |
| Reflection Beam 1.0 | US-origin, Apache 2.0 coding model | SWE-bench Pro 65.5 (vendor); token-efficient | Self-host |
Agentic Automation & Tool Use
v5.0's knowledge-work category measures what most business agents actually do: read documents, fill spreadsheets, and drive SaaS tools.| Model | Strength | Evidence |
|---|---|---|
| Gemini 4 Argon | SaaS / workflow automation | #1 AutomationBench-AA (78%) |
| Claude Sonnet 5.5 | Document-heavy knowledge work | #1 AA-Briefcase (1,812 Elo) |
| Muse Wonder Full | Long PDF and report analysis | #1 GDP.pdf (33%) — subscription only |
| Claude Haiku 5.5 / GPT-6 Luna | Cheap sub-agents and tool-call routing | $0.10 / $0.50 each |
| Decision models (Clef, d1) | Picking the tool, not running it | Typed, calibrated answers in 8–200 ms — see decision & routing |
Open-Weight Frontier: Self-Hosting at Scale
These are the models to run on your own multi-GPU servers or through any inference provider. All are sparse mixture-of-experts: memory scales with total parameters, speed with active parameters.| Model | AA v5.0 | Total / active | License | Notes |
|---|---|---|---|---|
| DeepSeek V4.1 Flash-1017 | 32 | 552B / 16B | MIT | Multimodal; cheapest first-party API ($0.15/$0.60 off-peak) |
| GLM-5.3 | 32 | 753B / 40B | Custom GLM license | Strongest open agentic model in August; weights since Aug 28 |
| MiMo-V2.6-Pro | 30 | 1.02T / 42B | MIT | Was #1 open on v4.3; Flash sibling is 310B / 15B |
| Ling 3.1 Flash-1019 | 29 | 560B / 25B | MIT | Ant Group / InclusionAI |
| MiniMax-M3.1-Flash | 29 | 428B / 23B | Community license | Image + video input |
| Step 5 Preview | 29 | 600B / 27B | Apache-style + conditions | StepFun; text + vision |
| Mistral Large 4 | 26 | ~1T / 52B | Modified-MIT open-weight | EU-trained; multimodal; verbose |
| Muse Spark Open | 25 | 816B / 42B | Muse Model License | Meta's new open flagship |
| Reflection Beam 1.0 | 18 | 501B / 23B | Apache 2.0 | US-origin; token-efficient |
| K2 Horizon 375B | 18 | 375B / 23B | Apache 2.0 | Fully open — weights, data, and code |
Local Inference by Hardware
What fits where, at 4-bit quantization unless noted. Rule of thumb: about 0.55–0.6 GB of memory per billion total parameters at 4-bit, plus a few GB for KV cache. For a walkthrough of what actually happens at load time, see Reading a vLLM Startup Log.| Hardware | Good fits | Notes |
|---|---|---|
| Phone, Jetson Orin Nano, Raspberry Pi-class (≤ 8 GB) | Gemma 4 E4B · Liquid d1-omni-600M · Nemotron 3.5 Bolt E4B | d1-omni is a decision model (classification/routing), not a chatbot |
| Laptop, 16–32 GB (Apple M-series or 8–12 GB GPU) | Gemma 4 12B · Liquid d1-3B · Strands Decider 2B · MiMo-V2.6-Distill-Qwen-9B | d1-3B answers decisions in ~30 ms on an M5 Pro (vendor) |
| One 24–48 GB GPU or 64 GB Mac | Qwen3.8 27B (AA 20) · Gemma 4 31B · Cloudflare Clef 27B via Ollama (~18–20 GB) | Qwen3.8 27B is the strongest dense model in this class on v5.0 |
| One 80 GB GPU or 128–192 GB Mac | gpt-oss-120B · Nemotron 3.5 Super VL (120B / 12B) · Kolibri-1 (78B FP8 — H200/B200 or 2× H100) | Low active-parameter MoEs run fast once they fit |
| 8-GPU node (H100 / H200 / B200) | DeepSeek V4.1 Flash · GLM-5.3 · MiMo-V2.6 · Mistral Large 4 (NVFP4) · Beam (NVFP4) | The open-weight frontier; see the table above |
Small & Edge Models
"Small" now means two different things: compact open models you run yourself, and cheap hosted tiers from the big labs.| Model | Size / tier | Use it for |
|---|---|---|
| Gemma 4 E4B | ~4B effective, open | On-device assistants, offline multimodal |
| Gemma 4 12B | 12B, open | Laptop-class general use with image input |
| Qwen3.8 27B | 27B dense, open | Best quality you can run on a single consumer GPU |
| Liquid d1-3B / Strands Decider 2B | 2–3B, open decision models | Classification and routing at the edge |
| Claude Haiku 5.5 | Hosted small tier | Best hosted small model (AA 36) at $0.10 / $0.50 |
| GPT-6 Luna | Hosted small tier | Lowest-latency OpenAI tier at $0.10 / $0.50 |
| Gemini 3.8 Flash | Hosted fast tier | Multimodal throughput at $0.75 / $3.75 (intro) |
Decision & Routing Models
| Model | Size | Where | Median latency | Best for |
|---|---|---|---|---|
| Cloudflare Clef | 27B | Workers AI, Ollama, HF | 209 ms | Default pick; text + image; Jev-compatible API |
| Cloudflare Clef-flash | ~9B | Workers AI, HF | 39 ms | High-volume routing at $0.038/M input |
| Liquid d1-3B | 3B | llama.cpp, Jetson, HF | 8–30 ms | On-device decisions — add your own abstain threshold |
| Strands Decider 2B | 2B | pip, HF | ~115 ms | Best-calibrated small open model; full training recipe |
| Laya | 322M–421M | pip, HF | 7–33 ms | Fine-tuning base for narrow classifiers |
| TypeSafe Jev | Closed | API | ~250–520 ms | The incumbent the others benchmark against |
Speed & Low Latency
- Mercury 2.5 (Inception) — a diffusion LLM that drafts many tokens in parallel; ~1,100 tok/s per Inception at $0.20/$0.75 (promo $0.04/$0.15). Not yet independently benchmarked; best for summarization, compaction, and extraction at volume.
- Gemini 3.8 Flash, Claude Haiku 5.5, GPT-6 Luna — the hosted fast tiers; pick by ecosystem.
- Kimi K3.1 Pro Highspeed — a faster serving tier of K3.1 Pro at $4/$20.
- Decision models — if the answer is a label, a decision model in 8–200 ms beats any generative model.
Long Context
One million tokens is now table stakes: every current Claude model, GPT-6/6.1, Gemini 4, Kimi K3.1 Pro, and most open-weight flagships advertise it. The outliers are Llama 4 Scout (10M tokens, open weights), Grok 4.1 Fast (2M), and Gemini 4 Argon, which can also write up to 1M output tokens. Caveat: many models are trained or RL-tuned at 256K and extrapolate beyond it, so test recall on your own documents before relying on the full window.Budget & High-Volume APIs
| Model | AA v5.0 | $/M in / out | Notes |
|---|---|---|---|
| Claude Haiku 5.5 | 36 | $0.10 / $0.50 | Prompts over 100K tokens cost $0.50 / $2.50 |
| DeepSeek V4.1 Flash-1017 | 32 | $0.30 / $1.20 | Half price off-peak ($0.15 / $0.60); MIT weights |
| MiMo-V2.6-Pro | 30 | $0.435 / $0.87 | Flash sibling at $0.14 / $0.28 |
| MiniMax-M3.1-Flash | 29 | $0.15 / $0.60 | Image + video input |
| Ling 3.1 Flash-1019 | 29 | $0.30 / $0.90 | MIT |
| GLM-5.3-Flash | — | $0.15 / $0.50 | MIT; not yet on v5.0 |
| Mistral Large 4 | 26 | $0.70 / $2.10 | Verbose — check cost per task |
| GPT-6.1 Terra | 51 | $1 / $5 | The cheapest model above 50 |
| GPT-6.1 Sol | 55 | $2 / $10 | Best frontier value per task |
Sovereign & Regional Deployments
- EU: Mistral Large 4 (EU-trained and EU-hosted, all official EU languages, open weights) and Aleph Alpha Kolibri-1 (German-built English/German model with an EN/DE tokenizer, Apache 2.0, on-prem) — note Aleph Alpha agreed to merge with Cohere in September.
- Gulf: MBZUAI K2 Horizon — the largest fully open model, with training data and code published.
- US-origin open weights: Muse Spark Open (Meta), Reflection Beam 1.0, Nemotron 3.5 Super VL (NVIDIA), Gemma 4 (Google), gpt-oss-120B (OpenAI), and Inkling (Thinking Machines).
- China: DeepSeek, Z.ai, Xiaomi, Moonshot, MiniMax, StepFun, Ant, and Tencent still produce the strongest open weights; check each license before commercial use (GLM, MiniMax, and Muse licenses carry revenue or attribution conditions).
Conclusion
Three things to take from this update. First, re-check your assumptions whenever the benchmark changes: v5.0 leans on private agentic tests, and it reshuffled the field more than any single model launch did. Second, price per task beats price per token — GPT-6.1 Sol, Ember-1, and Haiku 5.5 all win by doing less work per answer. Third, not every call needs an LLM: decision models now handle routing and classification faster, cheaper, and with real confidence scores. Try the picks interactively in the model selector, and see the October new-models roundup for the models that don't fit on a leaderboard.Sources: Artificial Analysis leaderboards and model pages (fetched Nov 3, 2026), AA Intelligence Index v4.2, v4.3, and v5.0 methodology posts, and vendor announcements and pricing pages from Anthropic, OpenAI, Google, Meta, xAI, Moonshot, DeepSeek, Z.ai, Xiaomi, Alibaba, MiniMax, StepFun, InclusionAI, Mistral, Reflection AI, NVIDIA, MBZUAI, Aleph Alpha, Inception, Fireworks AI, Cloudflare, Liquid AI, and Strands Agents. Vendor-reported benchmarks are labeled as such.